
The prompt is the smallest part of the job.
I still see teams track generation time as if it were the primary cost center. The interface is open for a few minutes, takes appear, and the spreadsheet records a tidy service fee. Everything that happens before the prompt is written and everything that happens after the selected take is chosen is treated as background noise. That background noise is where most of the real work lives.
Between the moment someone decides to generate and the moment a file is ready to hand to an editor or finishing artist sits a sequence of human tasks that do not appear on the model’s pricing page. Counting those tasks is the only way to know what an AI-assisted shot actually costs a production team.
The Work That Sits Before the Prompt
Preparation is not optional overhead. It is the first labor block.
Brief interpretation and the decision about what the test is meant to prove
Writing the locked list and the flexible list
Building and labeling the reference package
Setting the variation budget and the selection criteria
Writing the one hypothesized note that will be used to test revisability
On a disciplined pilot this block often consumes more person-hours than the generation cycle itself. When it is skipped or rushed, the generation cycle simply produces attractive takes that later require extra cycles to correct.
I time this work separately. It is the cheapest place to spend effort and the most expensive place to discover a mistake.
The Work That Sits Inside the Generation Cycle
Generation is not only the minutes the model is running.
Someone has to:
Monitor the queue and manage the variation set
Review takes at full resolution, not just thumbnails
Discard obvious failures and note the reasons
Protect the fixed budget so the set does not expand under enthusiasm
Failed and discarded takes belong in the cost. They consumed service credits and human attention. Treating only the final selected take as the cost of generation understates the work by a wide margin.
The Work That Sits Between Selection and Export
This is the block most often left uncounted.
Internal selection against written criteria
Assigning the Demo-Quality / Conditional / Candidate mark
Writing the revision-scope statement
Applying the pre-written note and recording whether it stayed local
Performing any cleanup required before the take can leave the generation environment
Writing the short handoff note that travels with the file
Confirming the take still meets the original criteria after the revision test
Only after these steps is the file ready for an editor or finishing artist to receive it without a long verbal explanation. That is the export point that matters for a production pipeline. Everything before it is still internal process.
A Simple Counting Method That Fits on One Page
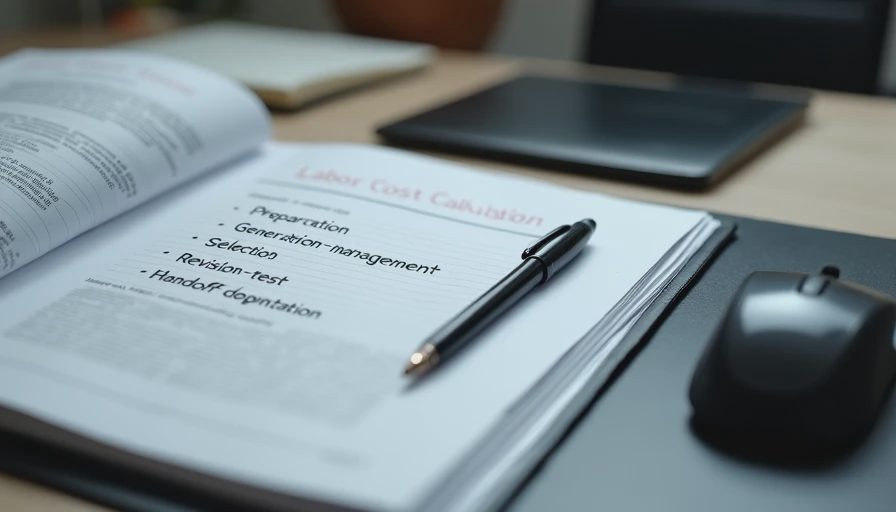
I use five labor buckets and one service-cost line:
Preparation hours
Generation-management hours (including review of discarded takes)
Selection and marking hours
Revision-test and cleanup hours
Handoff-documentation hours
Plus:
Generation service cost for the entire variation set
The sum of the five labor buckets, multiplied by the relevant internal rates, plus the service cost, is the fully loaded cost of reaching an exportable take. I do not include later finishing or client delivery in this particular count; those belong to the next stage of measurement.
The method is deliberately coarse. It is accurate enough to reveal where time is actually going and simple enough that a small team will actually use it under deadline pressure.
What the Numbers Usually Show
Across the controlled pilots I have measured with small agency teams, the pattern is consistent.
Preparation and the revision-test block together often equal or exceed the generation-management time. Selection is short when criteria are written in advance and long when they are not. Handoff documentation is the smallest number and the one most frequently skipped—until the editor asks basic questions that should have been answered in a ten-minute note.
Service cost is real and should be tracked. In every pilot so far it has been smaller than the fully loaded labor once normal agency rates are applied.
The teams that improve their numbers fastest are not the ones that generate fewer takes. They are the ones that tighten preparation and force the revision test to happen before anyone falls in love with a brittle frame.
A Calibration Example
On a recent thirty-second product pilot the raw generation window looked efficient. The fully loaded count told a clearer story:
Preparation: 2.1 hours
Generation management: 0.9 hours
Selection and marking: 0.5 hours
Revision test and light cleanup: 1.4 hours
Handoff note: 0.3 hours
Total labor: just over five hours, plus the service cost of the variation set.
An earlier, less disciplined run on a similar brief produced a lower generation-management number and a much higher revision-test number because the note forced a full restart and a second selection cycle. The pictures were comparable. The counted work was not.
The dog slept through the accounting. Morgan looked at the two tallies and said the same thing she says about every project that claims to be “almost done”: the work that is not on the timesheet is usually the work that is still unfinished. She is right.
What to Count on the Next Pilot
Track the five labor buckets and the full service cost for the variation set. Do it on a synthetic brief first so the measurement itself does not carry client pressure. Compare the result to the simple baseline. The largest gap will tell you which part of the process between prompt and export still needs attention.
The prompt is easy to write. The exportable take is the one that has survived preparation, selection, a realistic note, and a clear handoff. Until those steps are counted, the team is still measuring the wrong part of the job.
If it cannot survive the handoff, it is not a workflow yet.
No letters yet — be the first to write.